

Only available on the Enterprise planThis feature is only available on the Enterprise plan. Review our plans and pricing or sign up for our free expert-led trial today.
How organization data is structured
Organization data has three layers:- A bucket is your cloud storage: S3, Google Cloud Storage, Azure Blob Storage, or any S3-compatible service. Edge Impulse connects to it with credentials you supply.
- A dataset is a pointer to a path inside that bucket, plus the metadata Edge Impulse keeps about it. Creating a dataset does not copy or move your files. Your bucket stays the source of truth, and files added to that path by any other tool show up in Edge Impulse.
- A project import copies files from the dataset into a project, converting them to a format the ingestion service accepts.
Health reference design
We have built a health reference design that describes an end-to-end ML workflow for building a wearable health product using Edge Impulse. In this reference resign, we want to help you understand how to create a full clinical data pipeline by using a public dataset from the PPG-DaLiA repository. This tutorial will guide you through the following steps:- Synchronizing clinical data with a bucket
- Validating clinical data
- Querying clinical data
- Transforming clinical data
- Building data pipelines
Buckets
Before we get started, you must link your organization with one or more storage buckets. Further details about how to integrate with cloud storage providers can be found in the Cloud data storage document.Datasets
Two types of dataset structures can be used - Generic datasets (default) and Clinical datasets.There is no required format for data files. You can upload data in a wide range of formats, whether it’s CSV, Parquet, or a proprietary data format.However, to import data items to an Edge Impulse project, you will need to use the right format as our studio ingestion API only supports these formats:
- JPG, PNG images
- MP4, AVI video files
- WAV audio files
- JSON/CBOR files in the Edge Impulse data acquisition format
- CSV files
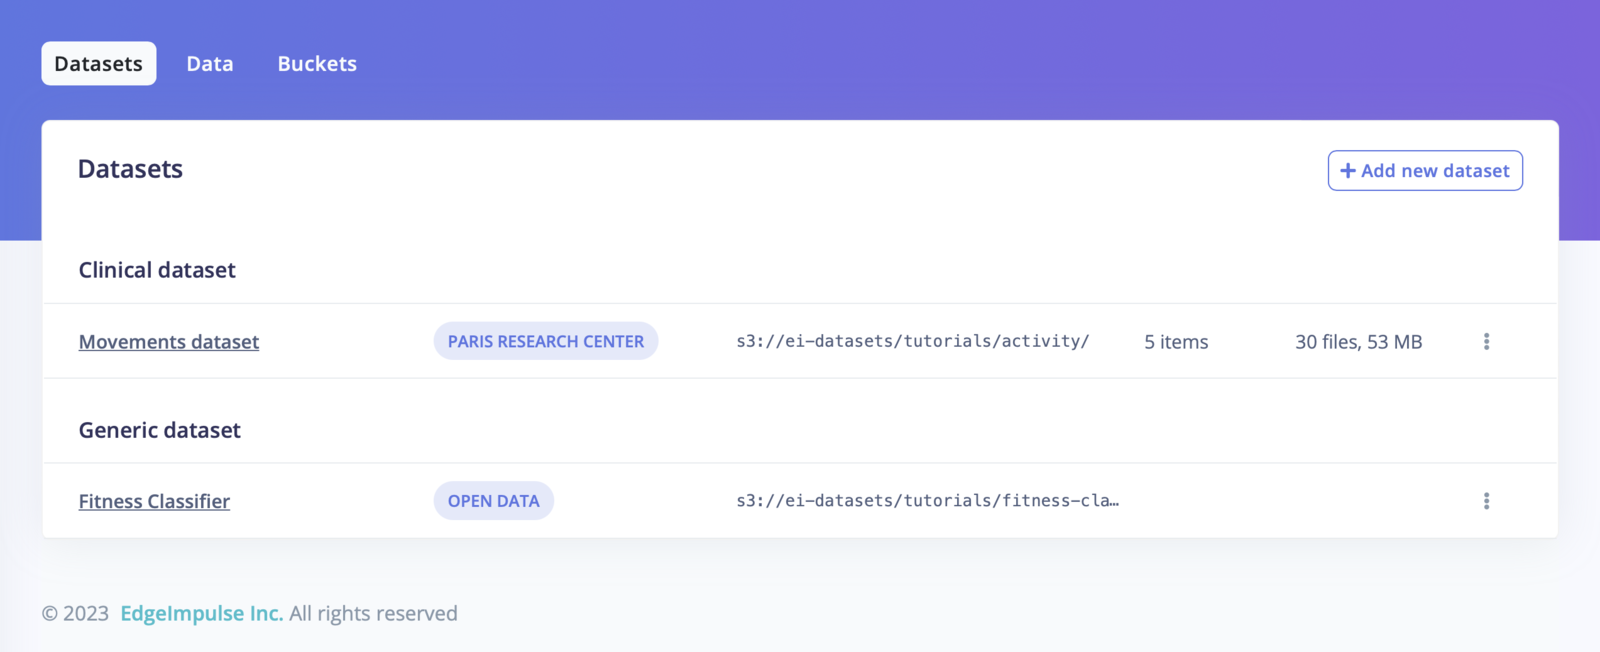
Datasets overview
- Default dataset
- Clinical dataset
The default dataset structure is a file-based one, no matter the directory structure:For example:or:Note that you will be able to associate the labels of your data items from the file name or the directory name when importing your data in a project.
Create a new dataset
Once you successfully linked your storage bucket to your organization, head to the Datasets tab and click on + Add new dataset: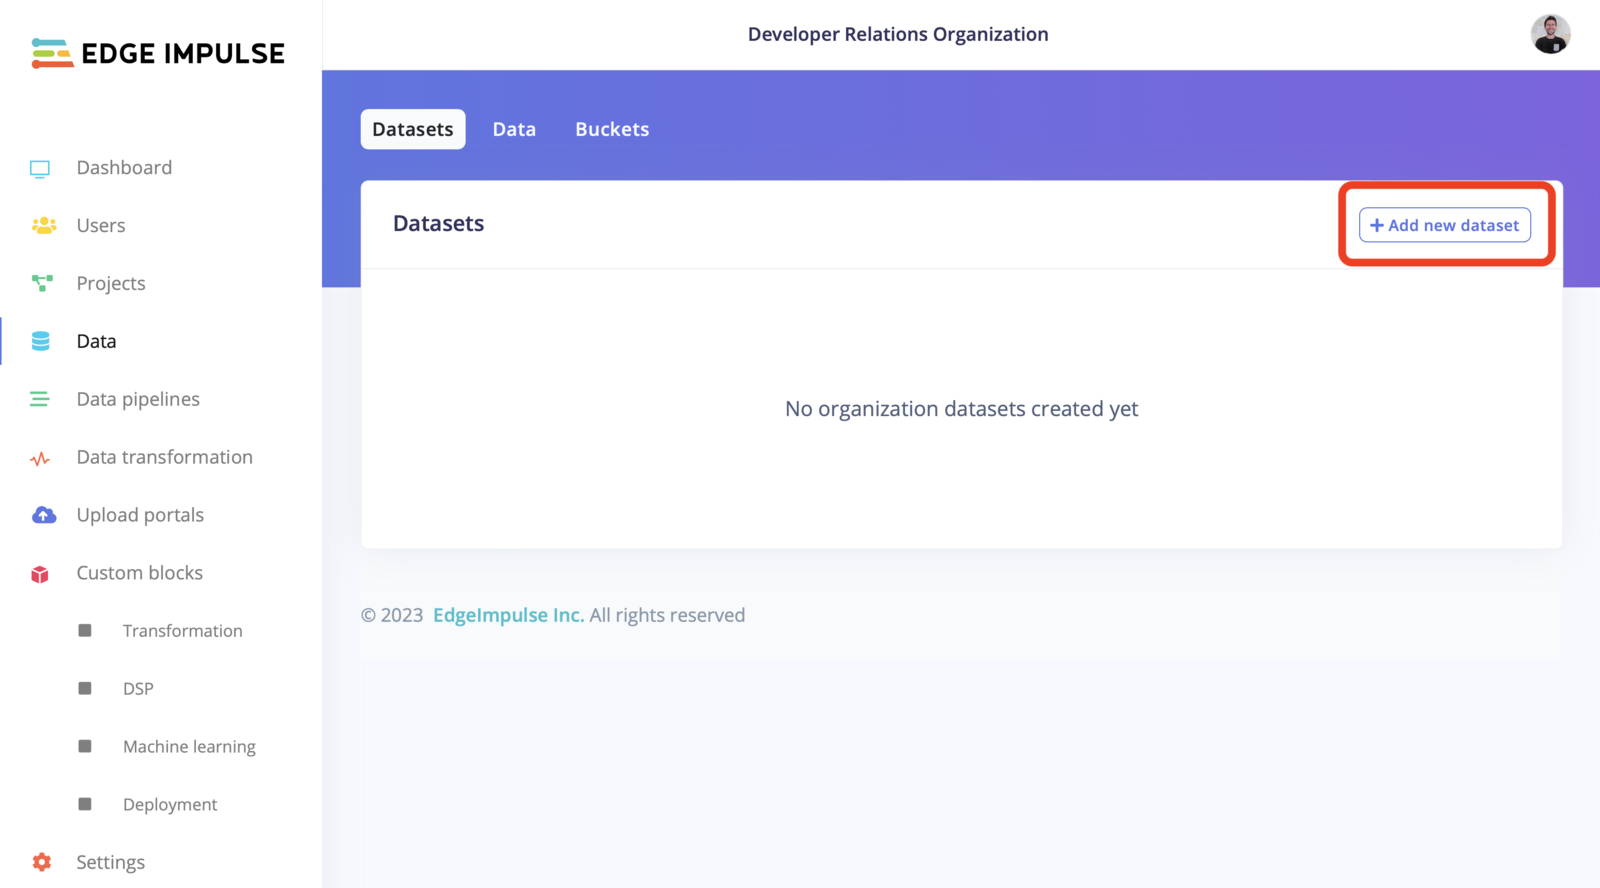
Add new dataset
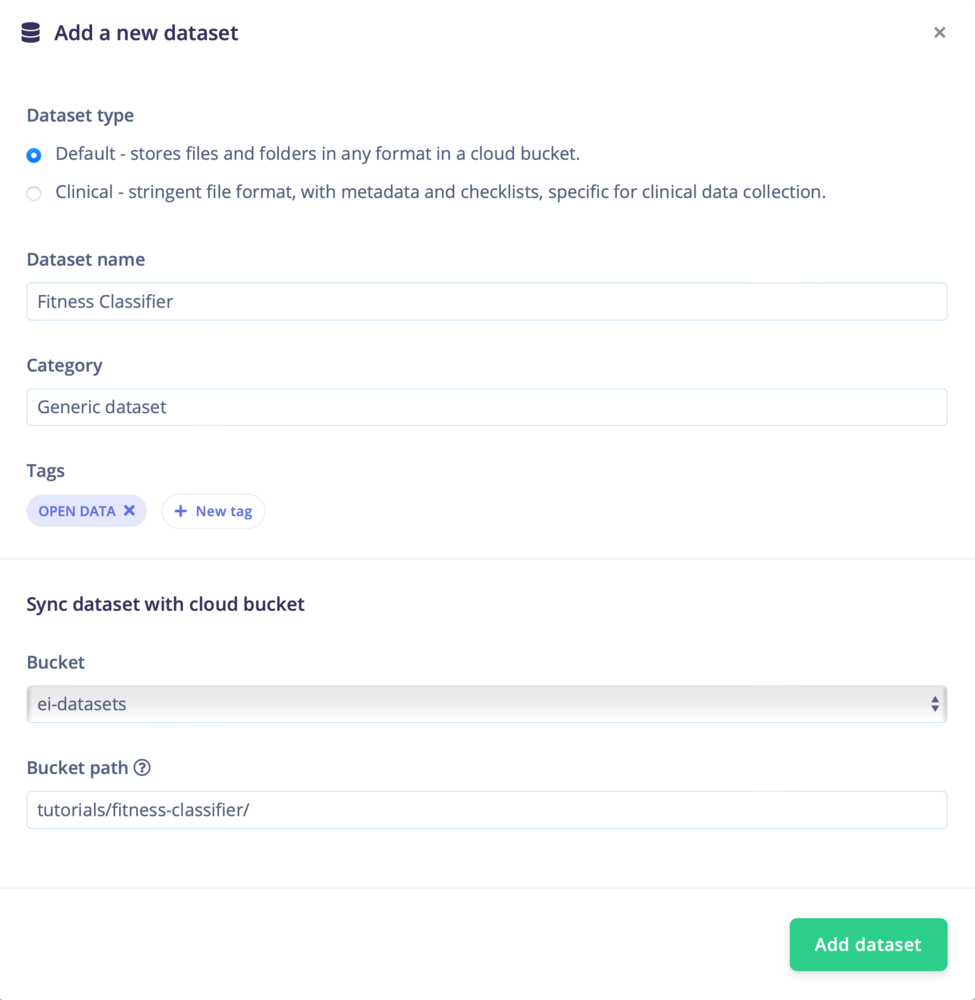
Add dataset
Data
With your datasets imported, you can now navigate into your dataset, create folders, query your dataset, add data items and import your data to an Edge Impulse project.- Default dataset
- Clinical dataset
Default view
The default view lets you navigate in your bucket following the directory structure. You can create folders with the + New folder button. To add data, drag and drop files and folders onto the right panel, and they upload to your bucket automatically.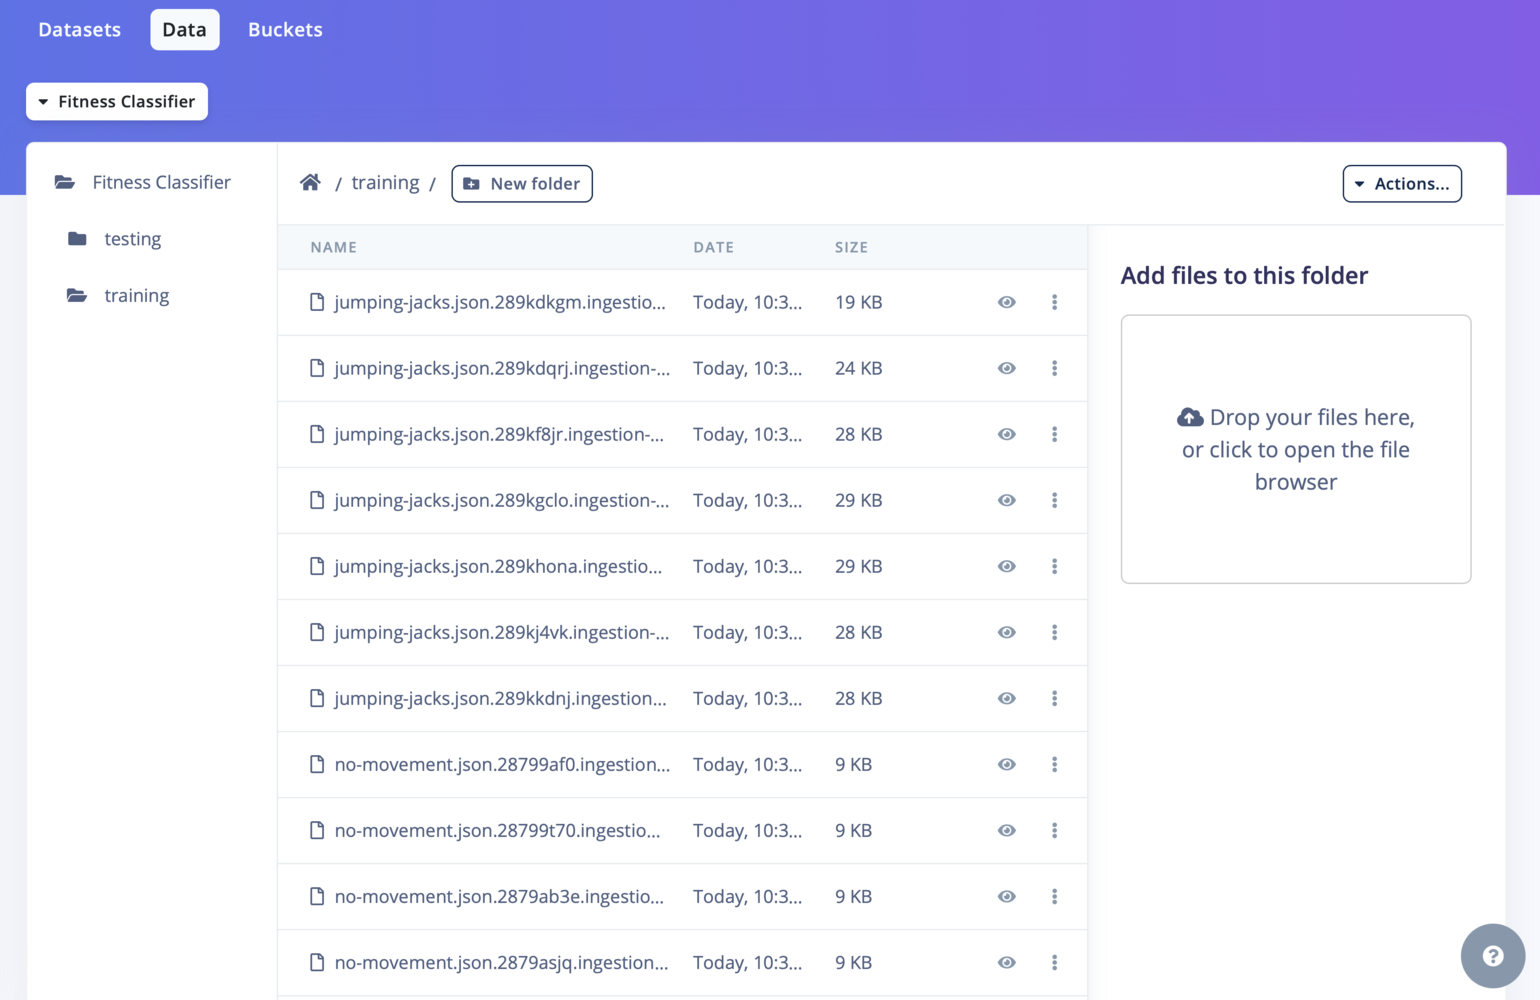
Data items overview
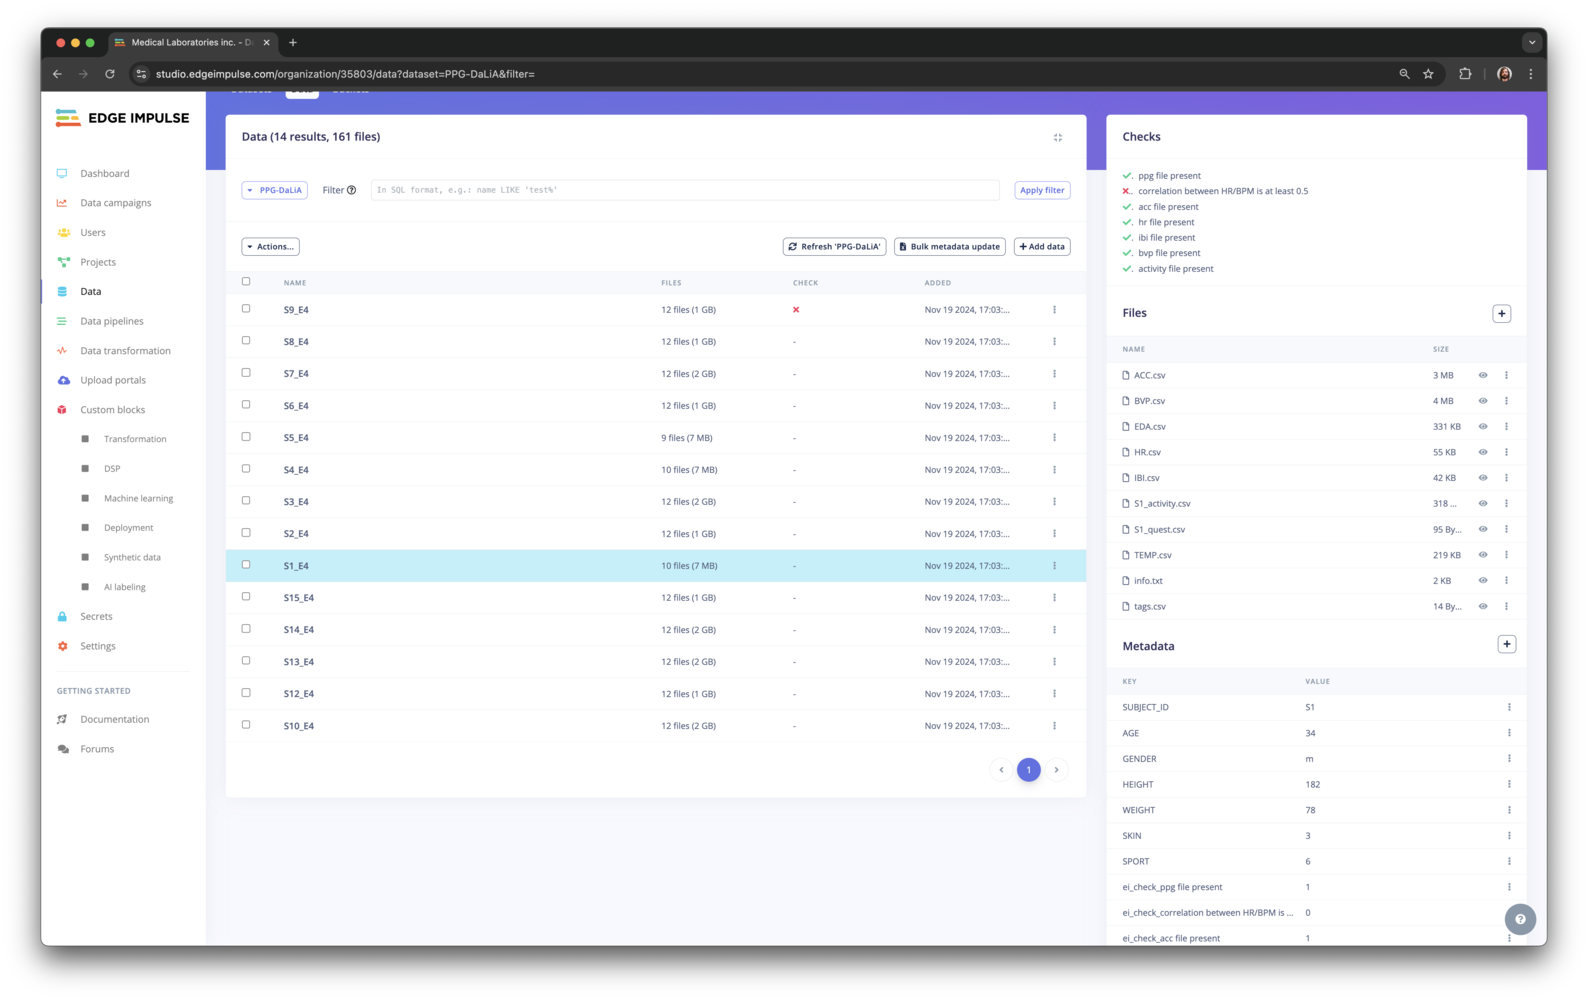
Adding data to your project
Go to the Actions…->Import data into a project, select the project you wish to import to and click Next, Configure how to label this data: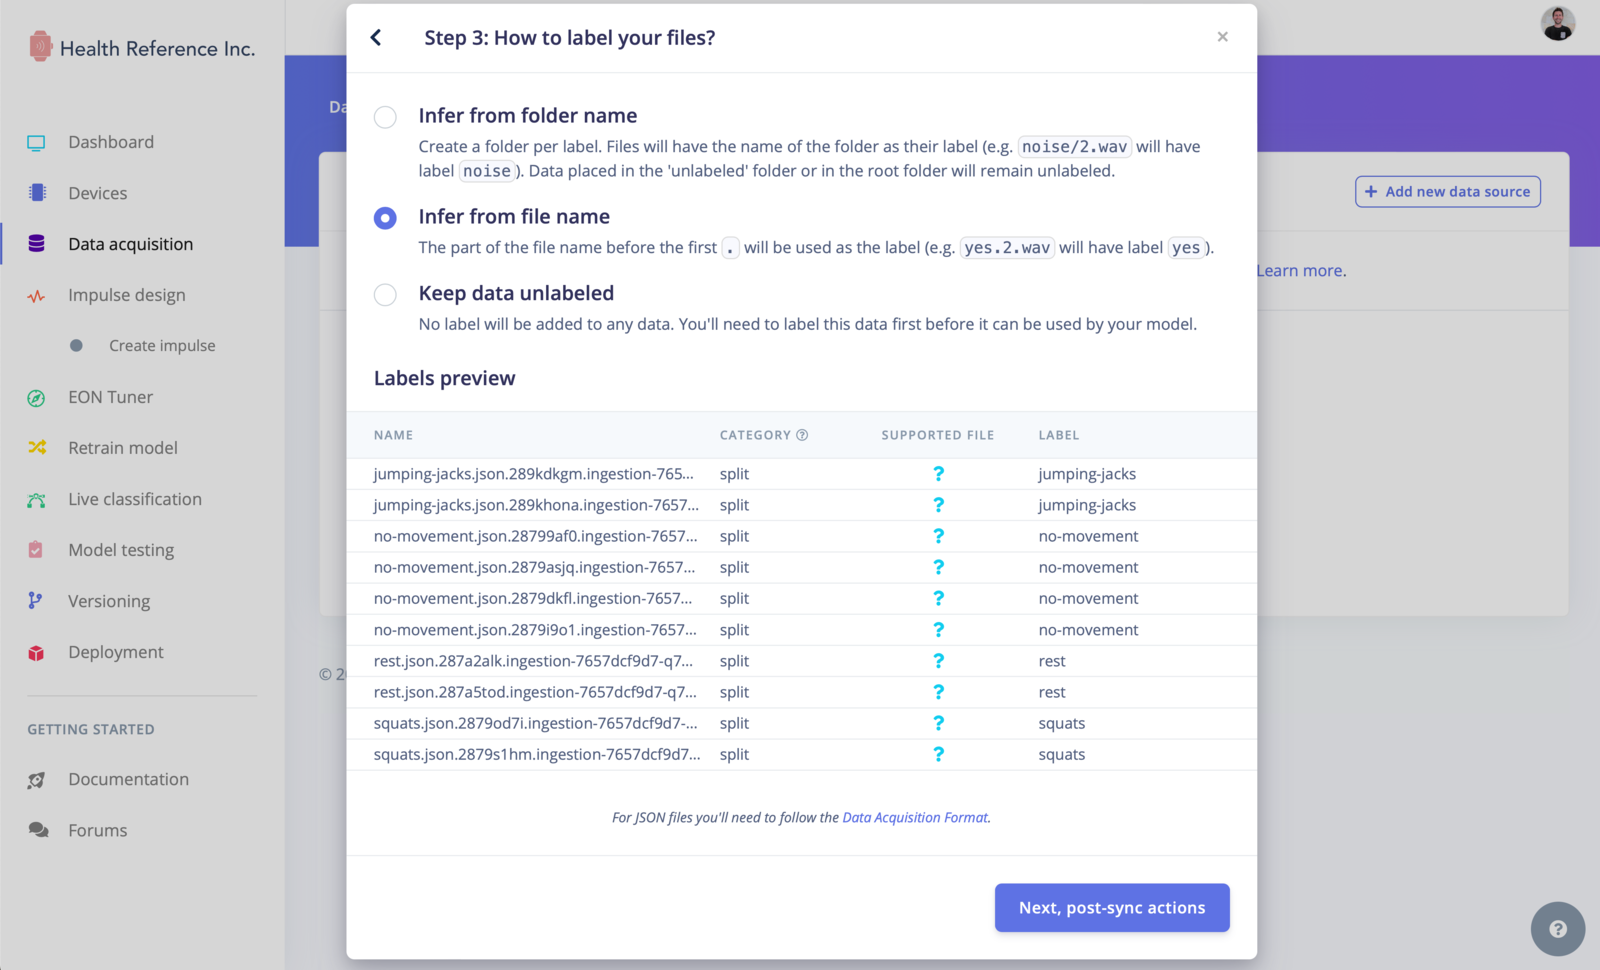
Uploading Files
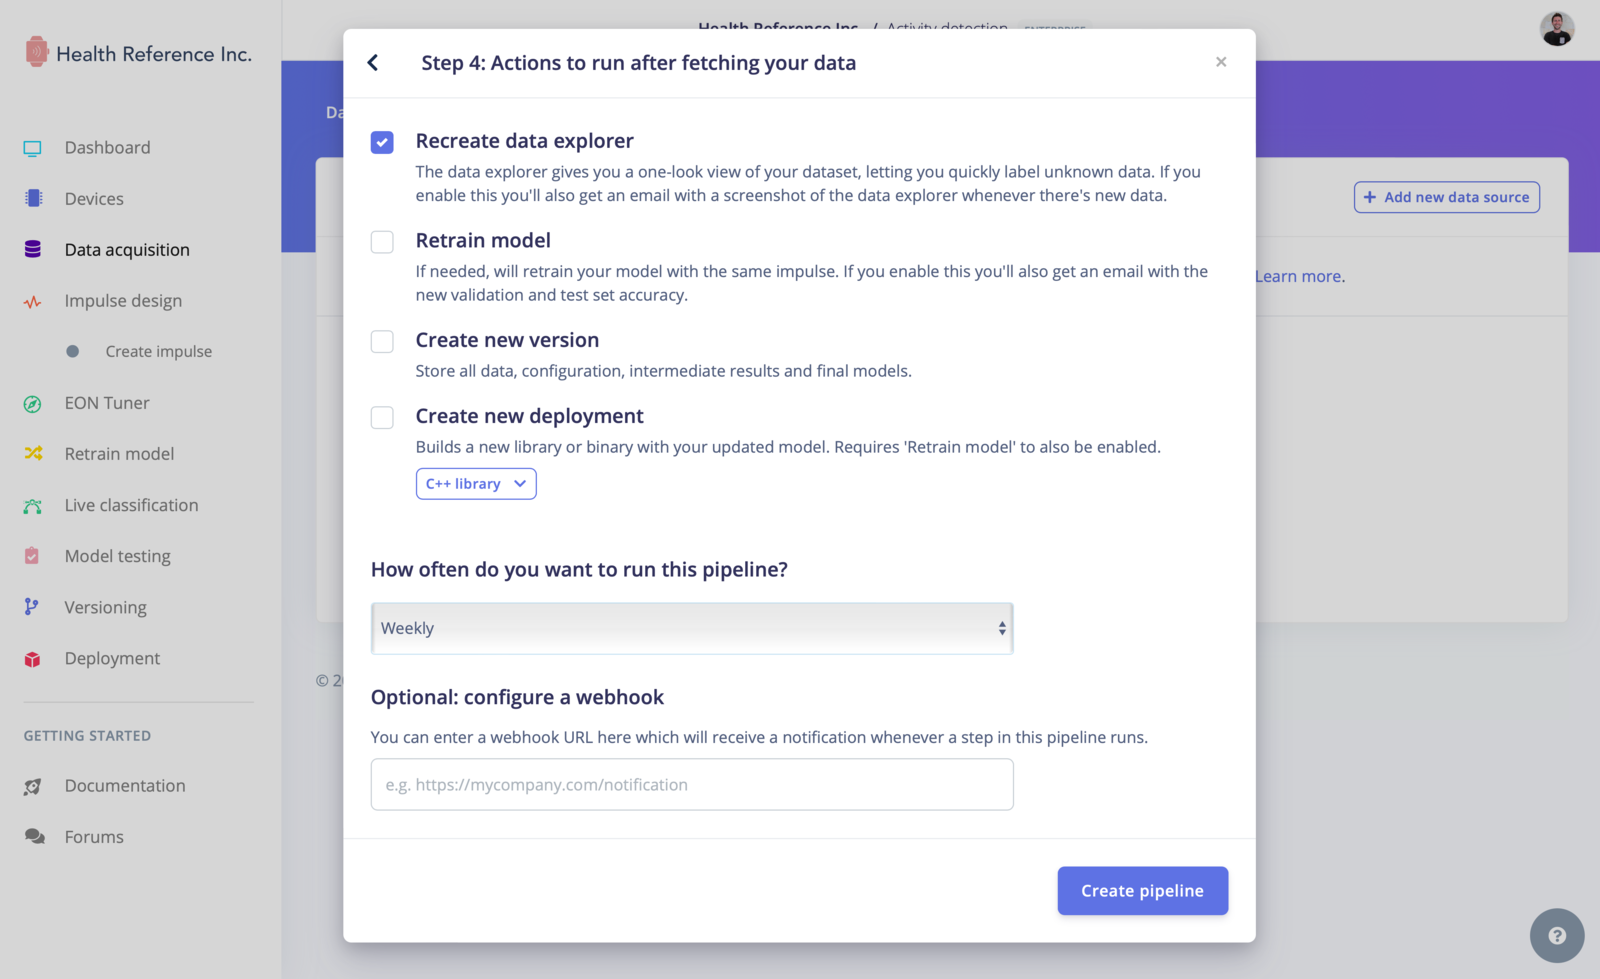
Label your files
Previewing data
We also have added a data preview feature, allowing you to visualize certain types of data directly within the organization data tab. Supported data types include tables (CSV/Parquet), images, PDFs, audio files (WAV/MP3), and text files (TXT/JSON). This feature gives you a quick overview of your data and helps ensure its integrity and correctness.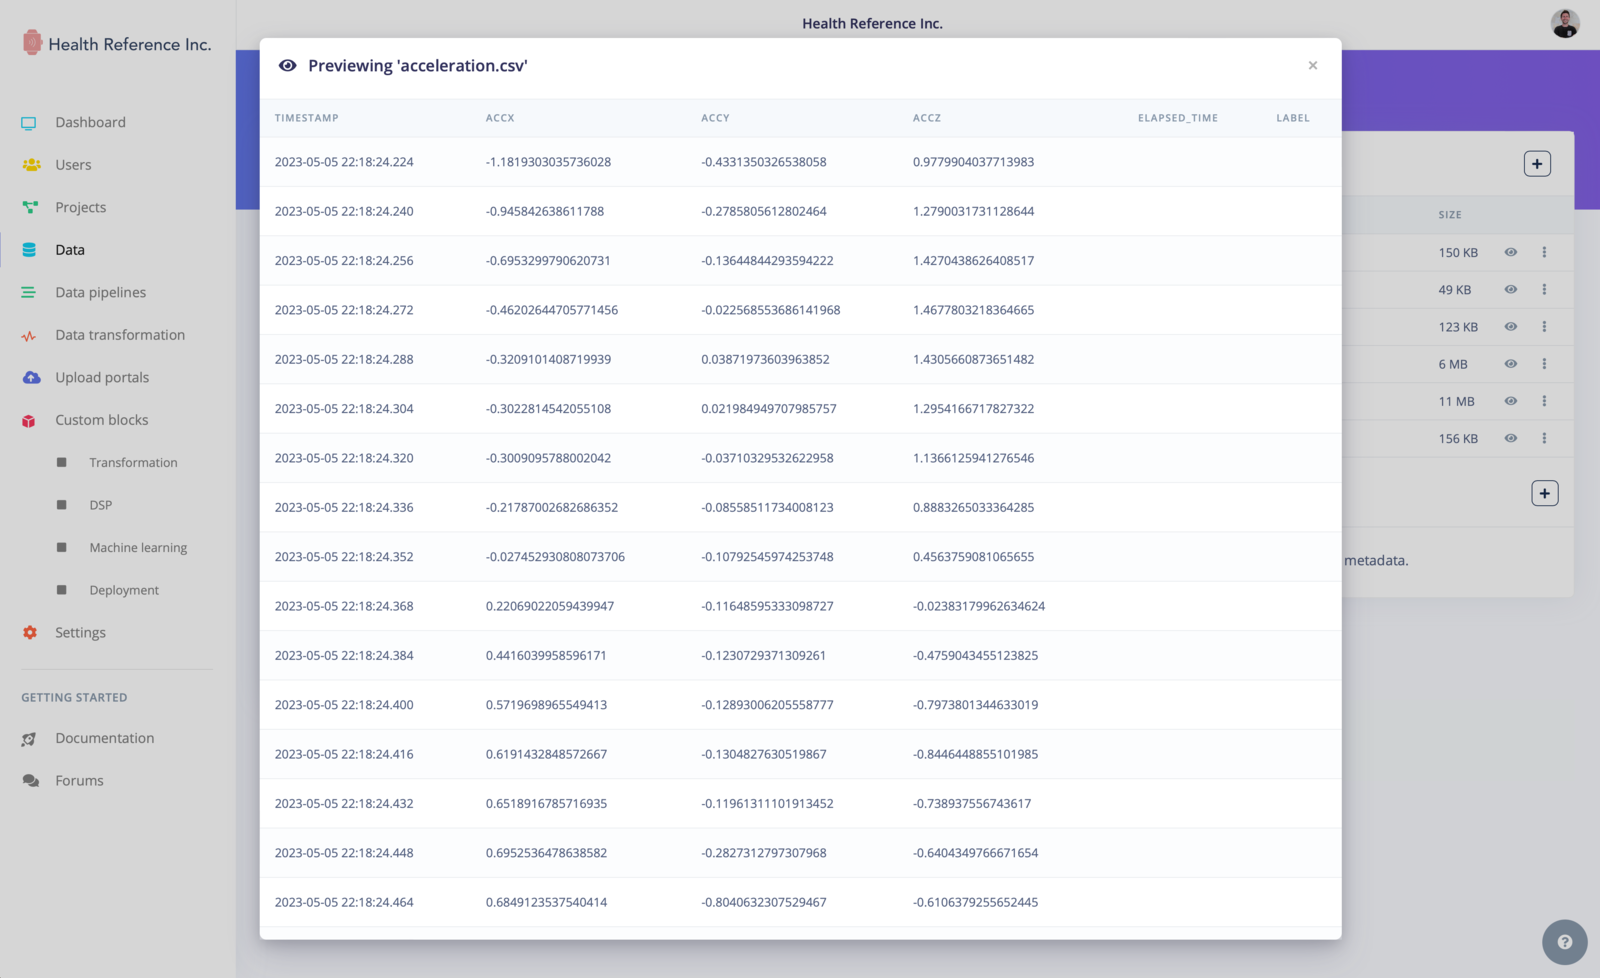
Data items overview - CSV/Parquet type
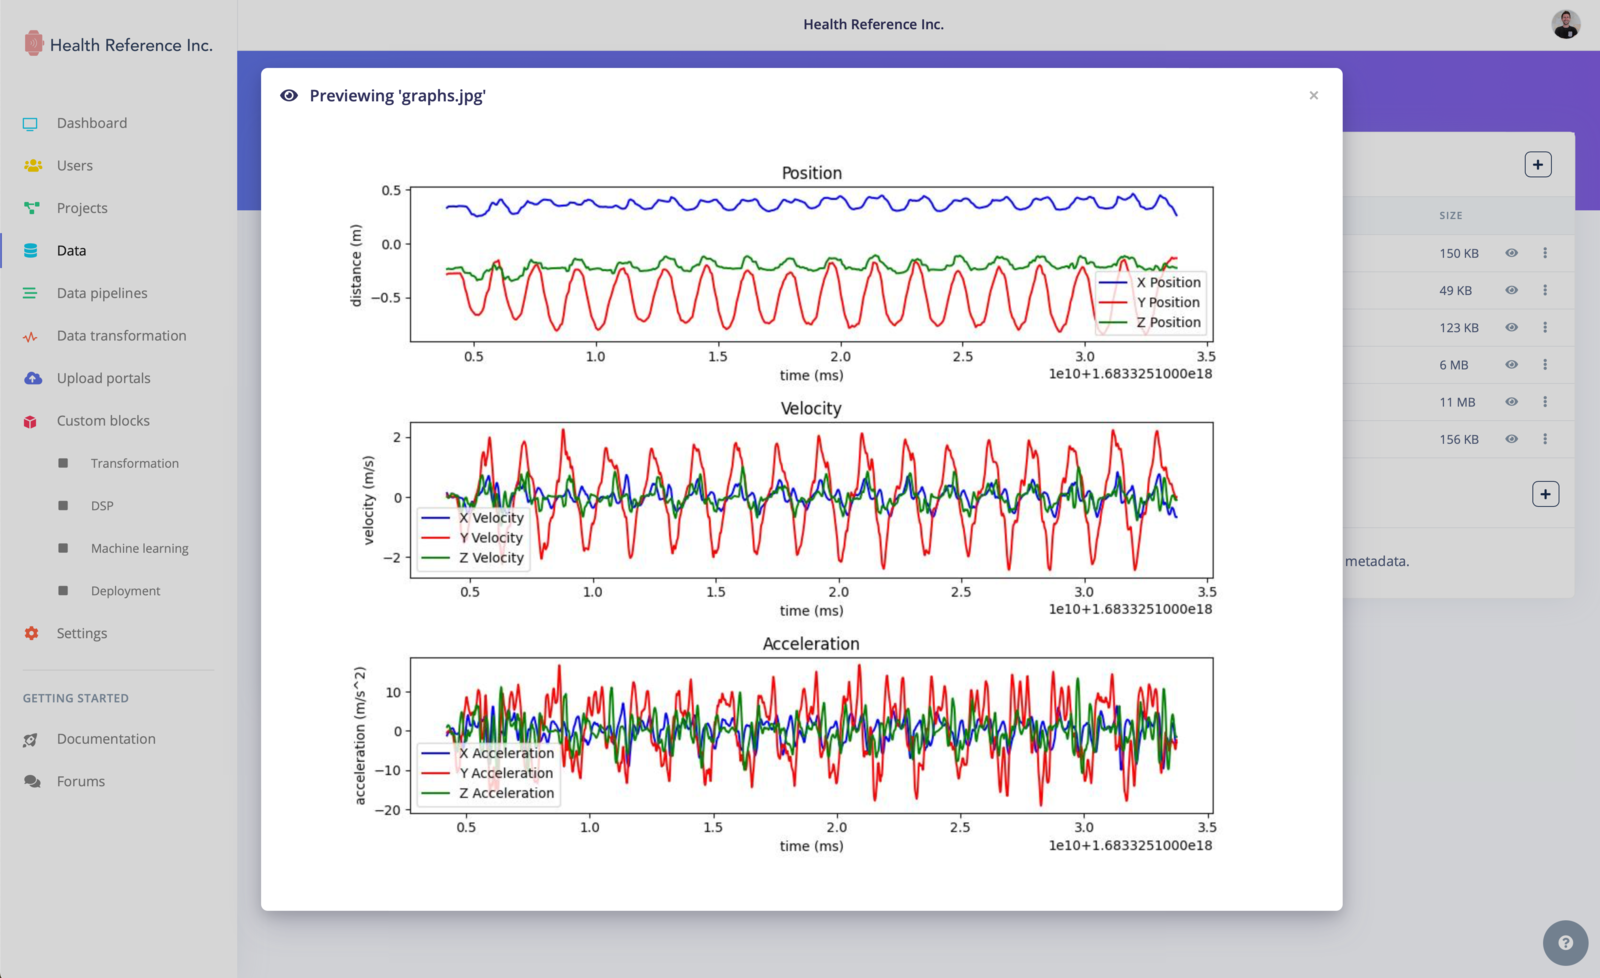
Data items overview - image type
API reference
Additional resources
- Cloud data storage for connecting a bucket
- Upload portals for letting external contributors add data
- Data pipelines for transforming datasets on a schedule
- Data campaigns for tracking how a dataset grows
- Health reference design for an end-to-end clinical workflow